Start with where the data lives
Suppose your analysis needs monthly customer revenue from orders stored in a shared database. SQL is often the natural place to filter and aggregate those records because the database already manages them. Downloading every order into a notebook before selecting one month adds movement, memory pressure, and another copy to protect.
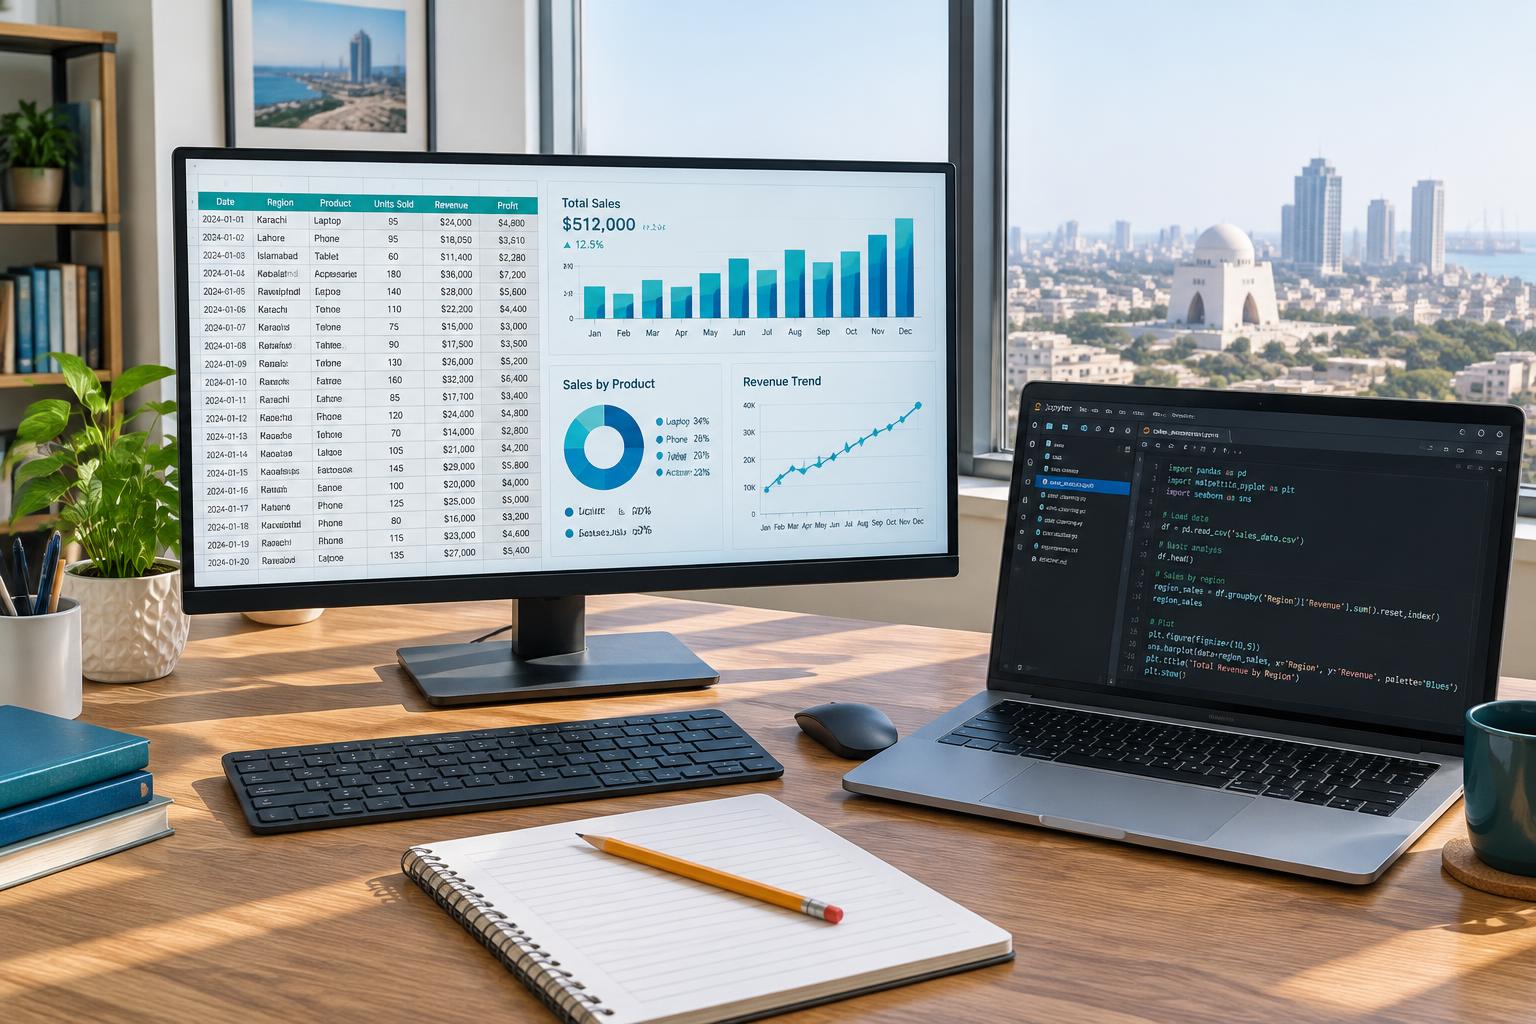
Now suppose the input is a small authorized CSV requiring exploratory text cleanup and a statistical chart. pandas may be a comfortable fit because it integrates with Python's analytical tools. Neither choice is a declaration that one language is better. The useful question is which execution location and workflow make this particular transformation understandable, reliable, and economical.
Translate the same small task both ways
Build a tiny fixture with customer_id, order_date, status, and amount. In SQL, filter completed orders, group by customer, and sum amount. In pandas, filter the same rows, group by customer_id, and sum the amount column. Compare sorted outputs rather than screenshots so differences become visible.
The pandas documentation provides direct comparisons between SQL operations and DataFrame operations. [1](https://pandas.pydata.org/docs/getting_started/comparison/comparison_with_sql.html) Use those examples to learn the correspondence, but still check data types and missing values. A familiar-looking expression is not proof that two systems handle nulls, dates, or numeric precision identically.
Treat joins as a data-modeling decision
Before joining customers to orders, state the intended relationship: one customer may have many orders, while each order should reference one customer. Count rows and inspect key uniqueness before and after the join. Duplicate customer keys can multiply order rows and inflate revenue without producing an execution error.
In pandas, use merge validation when the expected relationship is known, such as validate='many_to_one' for orders joined to unique customers. The merge documentation also warns that null keys can match each other, unlike usual SQL join behavior. [2](https://pandas.pydata.org/docs/reference/api/pandas.merge.html) Include null keys in your fixture so this difference cannot remain hidden until production data arrives.
Choose a sensible handoff boundary
A practical hybrid workflow uses SQL to select needed columns, apply date restrictions, and produce a moderately sized aggregate, then uses pandas for exploratory analysis and visualization. Save the query and its parameters with the notebook or script. Avoid embedding an unrecorded manual export between the two stages.
For repeated reporting, consider keeping stable business definitions in a shared database transformation rather than duplicating them across personal notebooks. For experimental features, Python code may be easier to iterate and test. Make the handoff explicit: input schema, row grain, time zone, currency, and refresh date should travel with the dataset so later calculations do not rely on memory.
Measure memory and runtime before optimizing
A file's compressed size is not the same as its in-memory footprint. String columns, temporary copies, and joins can substantially change memory requirements. Load a representative sample, inspect types, and estimate the full workflow rather than only the initial read. Select columns and aggregate early when those choices preserve the intended result.
Do not assume every SQL query is efficient or every pandas operation is slow. Database indexes, execution plans, network transfer, Python object types, and transformation structure all matter. Benchmark the complete path, including extraction and serialization. If a notebook is slow because it downloads unnecessary records, replacing one pandas expression will not solve the main problem.
Make the answer reproducible in either tool
Write checks for row counts, key uniqueness, accepted statuses, and total reconciliation. Compare a few hand-calculated customers and explain any excluded records. Parameterize the analysis date instead of silently using today's date, especially for a report that must be rerun later.
Publish a short decision note: SQL handles extraction and shared aggregation; pandas handles exploration and presentation; validation occurs at the boundary. If the project uses only one tool, explain why that is simpler. Competence means recognizing semantic and operational trade-offs, not forcing every problem into the tool you learned most recently.
Sources & further reading
Last editorial review: 27 October 2026. Examples are educational, not live employer data or guaranteed outcomes.